Text Data Collection

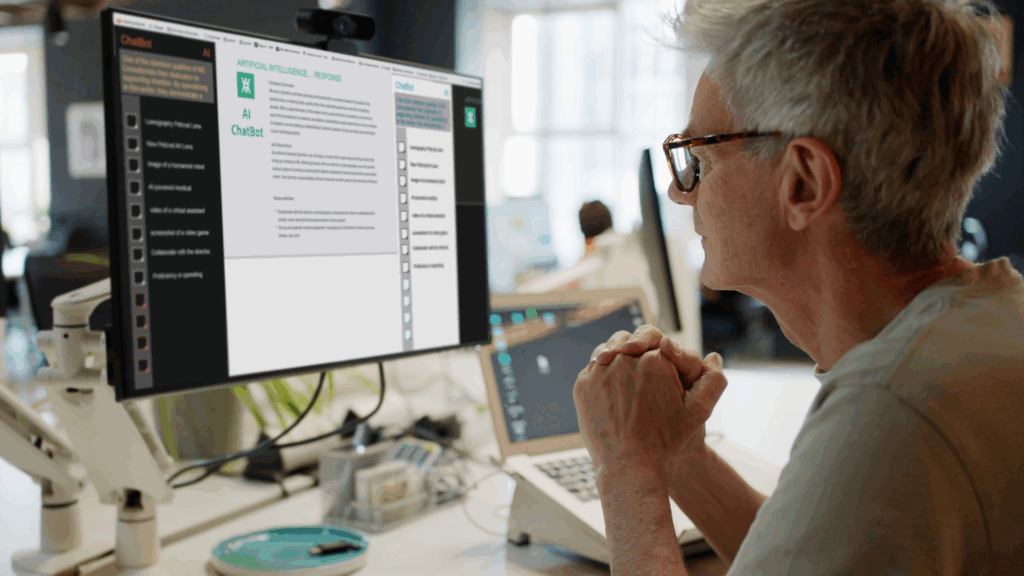
We deliver precisely high-quality labelled, human-annotated text datasets with emotion, entity, intent and context annotations leading to improvements in natural language processing (NLP), chatbots, and smart search systems.

Utilize Text Data to Drive Next Generation AI

In a world where organizations leverage text data to remain competitive, from known primary and secondary sources, to collecting text message, and hand-written text gives you even more data – all of which is unstructured, with most organizations not having the ability to derive learnings.

Data is not enough. Then through text annotation, text labelling and text data analysis, your organization can take unstructured data, and add the unprocessed raw data,

Utilize Text Data to Drive Next Generation AI

To return machine readable text data that minimum can give meaning, and maximum driving machine learning text data models, chatbots, intelligent systems powered by better analytic insights.

Statswork provides secure, scalable text data collection, annotation, and analysis—transforming complex text into useful insights.

Types of Text Data Collection we Offer:

Text data collection is the process of gathering text from various sources to train and enhance AI, NLP and machine learning systems. There are multiple distinctive forms of text data collection depending on the application and domain.

Industries

Text data collection allows industries to analyse customer sentiment, make improvements to their services, establish compliance, and create smarter, more reliable chatbots.

Why Select Statswork for Text Data Collection

Statswork delivers high-quality, customized text data collection solutions for AI and ML. Here’s why we’re the right choice:

Our Process for Text Data Collection

Our process ensures the delivery of accurate, high-quality text data tailored to your AI and ML needs maximizing impact at every stage.

Requirements discussion step icon Text data sourcing and collection icon Pre-processing step icon Quality assurance step icon Delivery and support step icon

1. Requirements Discussion:

We collaborate closely with your team to understand the specific text data needs of your AI/ML project, defining clear goals and target sources.
Requirements discussion illustration

2. Text Data Sourcing & Collection

We gather diverse and relevant text data from trusted sources such as articles, user reviews, chat logs, and more.
Text data sourcing and collection illustration

3. Pre-processing:

All collected text is cleaned, normalized, and pre-processed to ensure consistency and readiness for training.
Text pre-processing illustration

4. Quality Assurance:

We apply rigorous validation checks to maintain the integrity, relevance, and usability of the text data.
Quality assurance illustration

5. Delivery & Support:

Processed text datasets are delivered on time, with continued support for optimal use in your AI and ML models.
Delivery and support illustration

Success Stories

Insights - Must Read Articles

Data Collection | Article

Recognizing the differences between qualitative and quantitative data is vital for researchers, businesses, and students making decisions

Data Abstraction | Article

Data abstraction is essential for Database Management Systems (DBMS). It allows for the reduction of a complex database

Data Entry | Article

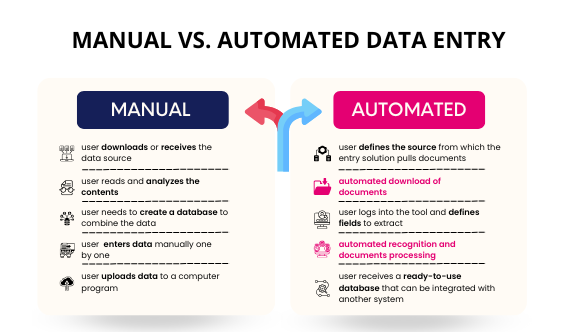
In 2025, organizations are standing at a crossroads between manual data entry and automated data entry solutions.

FAQs – Text Data Collection

1. What types of text data do you collect?

  • Web content (blogs, articles, forums)
  • Social media posts and comments
  • Customer reviews and feedback
  • Chat transcripts and messaging logs
  • Product descriptions and technical documents
  • Domain-specific or custom-requested text sources

2. Can you collect multilingual text data?

  • Yes, we support over 30+ languages
  • We have access to global sources for diverse language datasets
  • Text can be localized or region-specific based on your needs

3. How do you ensure the quality of the collected text data?

  • Rigorous data cleaning and preprocessing (removing noise, duplicates, etc.)
  • Manual and automated validation steps
  • Format standardization and structuring
  • Consistency checks to match project requirements

4. Is your text data collection customizable?

  • Yes, we tailor data collection to your industry, model type, and language
  • You can specify data type, source, format, and volume
  • We support both structured and unstructured text formats

5. How scalable is your text data collection service?

  • We handle everything from small pilot datasets to large-scale text corpora
  • Rapid deployment for urgent or high-volume projects
  • Infrastructure in place to support ongoing or recurring data needs

6. What is the typical turnaround time for a text data project?

  • Depends on volume, complexity, and language scope
  • Small to medium projects: 1–2 weeks
  • Large-scale or multilingual datasets: 3–6 weeks
  • We always agree on timelines upfront and deliver as scheduled

Need to enhance your ROI and customer experience? Connect with a trusted partner in qualitative market research, Insights Opinion.